Why Practical Data Annotation Matters Now and What a Data Annotation Specialist Actually Does
In today’s world of smart technology, artificial intelligence (AI) is everywhere. From phones that understand your voice to cars that drive themselves, AI makes many things possible. But for AI to work well, it needs good information. This information comes from data, and that data needs to be sorted and labeled. This sorting and labeling is called data annotation, and it’s super important.
Think of it like teaching a child. You show them a picture of a cat and say, "This is a cat." You do this many times until they learn what a cat looks like. AI learns in a similar way, but it needs many, many examples. If the examples are labeled wrong, the AI will learn the wrong things. This is why poor data annotation can make AI models work badly. Experts say that if the rules for labeling data are not clear, it can really hurt how well an AI performs RE for AI in Practice: Managing Data Annotation …. Also, the way data is annotated directly impacts how good an AI model turns out to be The influence of data annotation process.
This is where a data annotation specialist comes in. A data annotation specialist is a person who carefully labels different types of data. This could be pictures, videos, text, or sounds. They make sure each piece of data is tagged correctly so that AI systems can learn from it. Their work directly affects how accurate and reliable an AI model will be.
It’s a key step in what is data science, helping turn raw information into smart AI tools. If you are curious about what a data analyst does, you can find more information in our guide to what is a data analyst your 2026 career guide.
In 2026, the demand for well-trained data annotation specialists is growing. This guide will give you practical, step-by-step advice that you can use right away. We will look at how to do your job better, avoid common mistakes, and make sure the data you work with helps AI reach its full potential.
To stay on top of the latest advancements in AI and technology, consider subscribing to The AI Newsletter Worth Reading for clear daily updates.
A data annotation specialist does much more than just put labels on data. They are key players who make sure AI can understand the world correctly. Their daily work involves a mix of understanding complex ideas and making simple, clear instructions. This is a big part of what makes AI useful.
Translating Needs into Clear Tasks
One main job for a data annotation specialist is to take what the AI model needs and turn it into simple tasks for labeling.
Imagine an AI that needs to spot different kinds of cars. The person who builds the AI might say, "I need the AI to tell the difference between sedans, SUVs, and trucks." The data annotation specialist then takes this need and writes very clear rules for how to label pictures of cars.
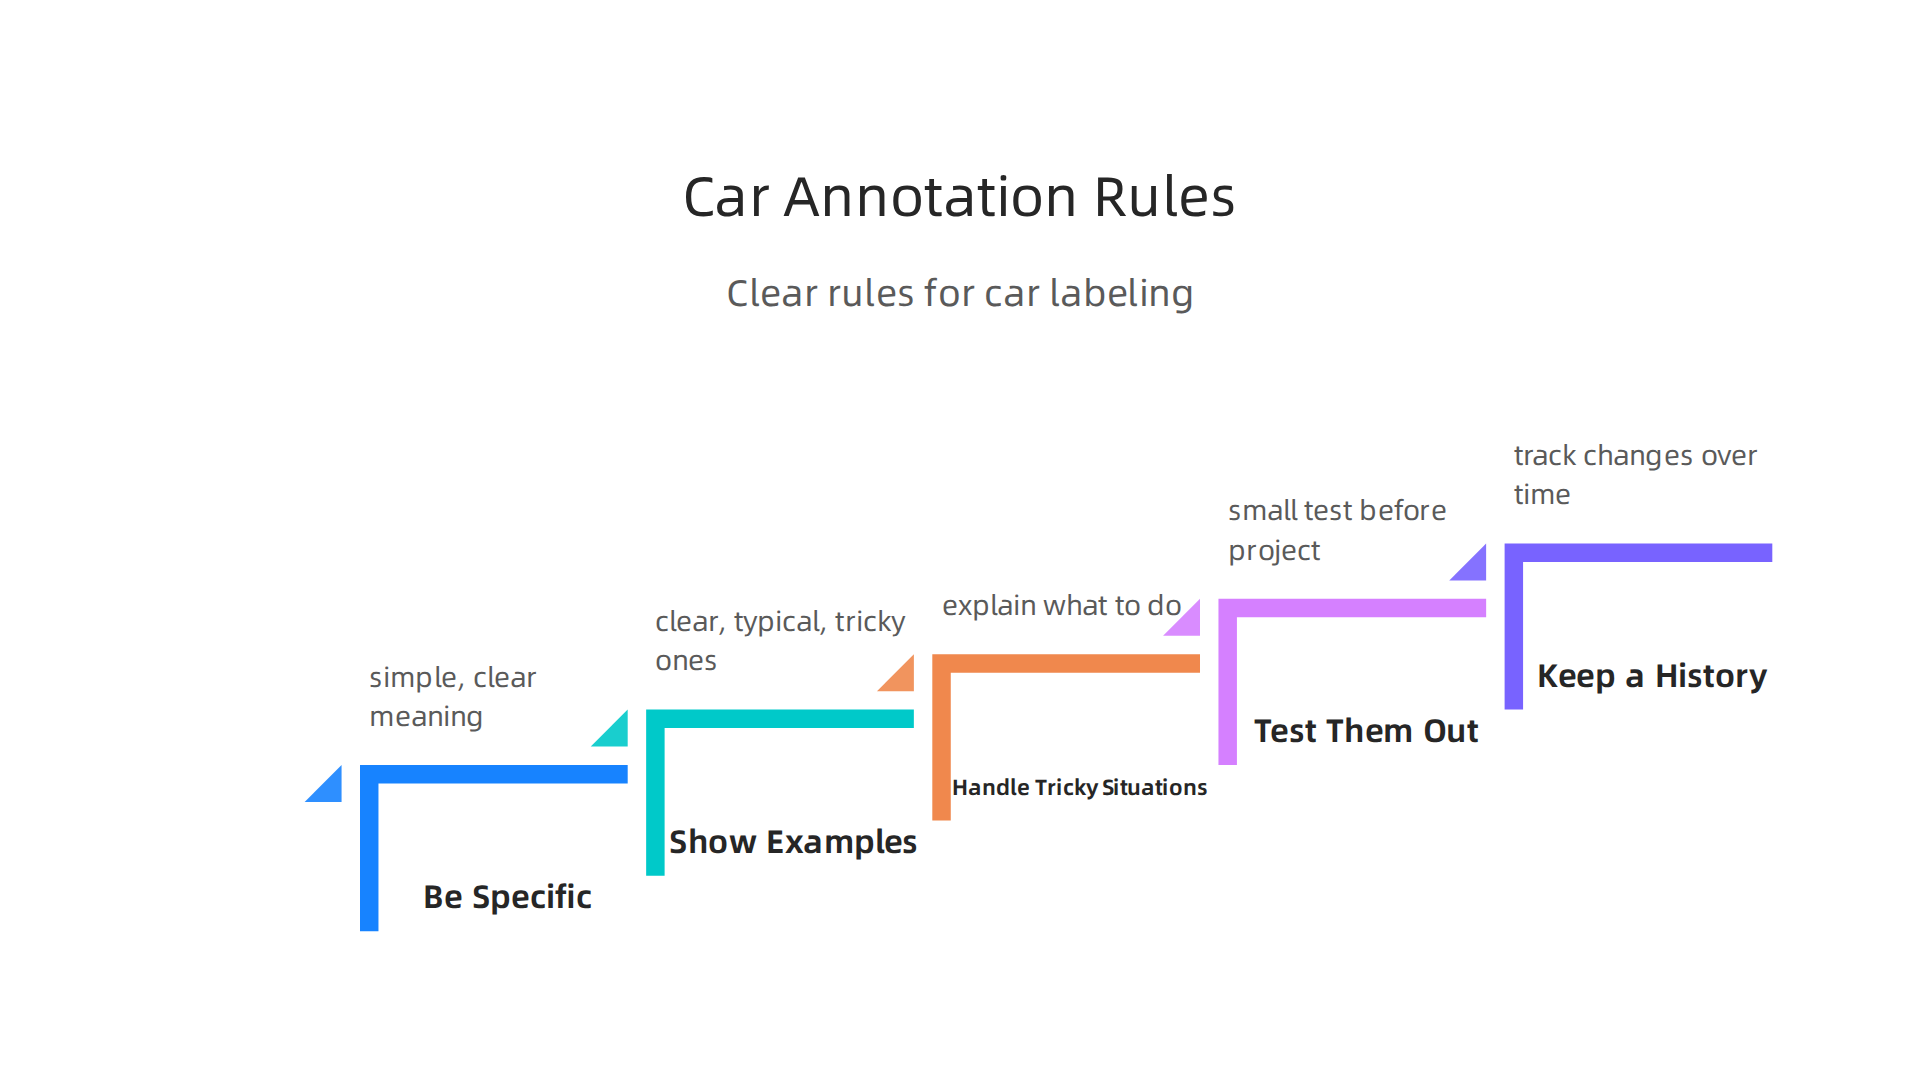
These rules might say:
- Draw a box around every car.
- Inside the box, pick "sedan," "SUV," or "truck."
- If you see a car that doesn’t fit these types, label it "other."
Without these clear rules, different people might label the same picture in different ways. This would confuse the AI and make it learn wrong. Poorly defined rules for data annotation can truly harm how well an AI model works RE for AI in Practice: Managing Data Annotation ….
Keeping Annotation Guidelines Updated
A data annotation specialist also creates and looks after the "annotation guidelines." Think of these as a playbook for labeling. They are detailed instructions that everyone follows. These guidelines need to be kept up-to-date as the AI project changes or as new kinds of data appear.
Part of this job includes running checks to make sure everyone is labeling in the same way. This is called Quality Assurance (QA) and Inter-Annotator Agreement (IAA).
- Quality Assurance (QA): This means checking the labeled data for mistakes. It’s like a teacher checking homework to make sure the answers are right.
- Inter-Annotator Agreement (IAA): This measures how much different people agree when labeling the same piece of data. If many people label the same picture of a cat as "cat," then the IAA is high. High IAA means the guidelines are clear and everyone understands them well Selecting the Right Inter-annotator Agreement Metric for …. If there’s a lot of disagreement, it means the rules might not be clear enough, or people need more training. Experts say that aiming for an IAA score above 0.8 shows strong consistency in labeling Aligning Annotation Goals….
These checks are very important because they help fix problems early. They ensure that the AI learns from a consistent and high-quality dataset. This work is a crucial part of the larger field, helping to define what is data science in a practical sense, by making sure the information AI uses is top-notch. Understanding why this step is so critical helps you grasp why data annotation tech is critical for AI accuracy.
Choosing annotation tools and platforms: evaluation criteria and trade-offs
After setting up clear rules and checking the work, a data annotation specialist also needs to pick the right tools for the job. Choosing the best annotation platform is a big part of making sure AI learns correctly and efficiently. In 2026, there are many options, and each has its own good and bad points.
Most tools for data annotation fall into three groups:
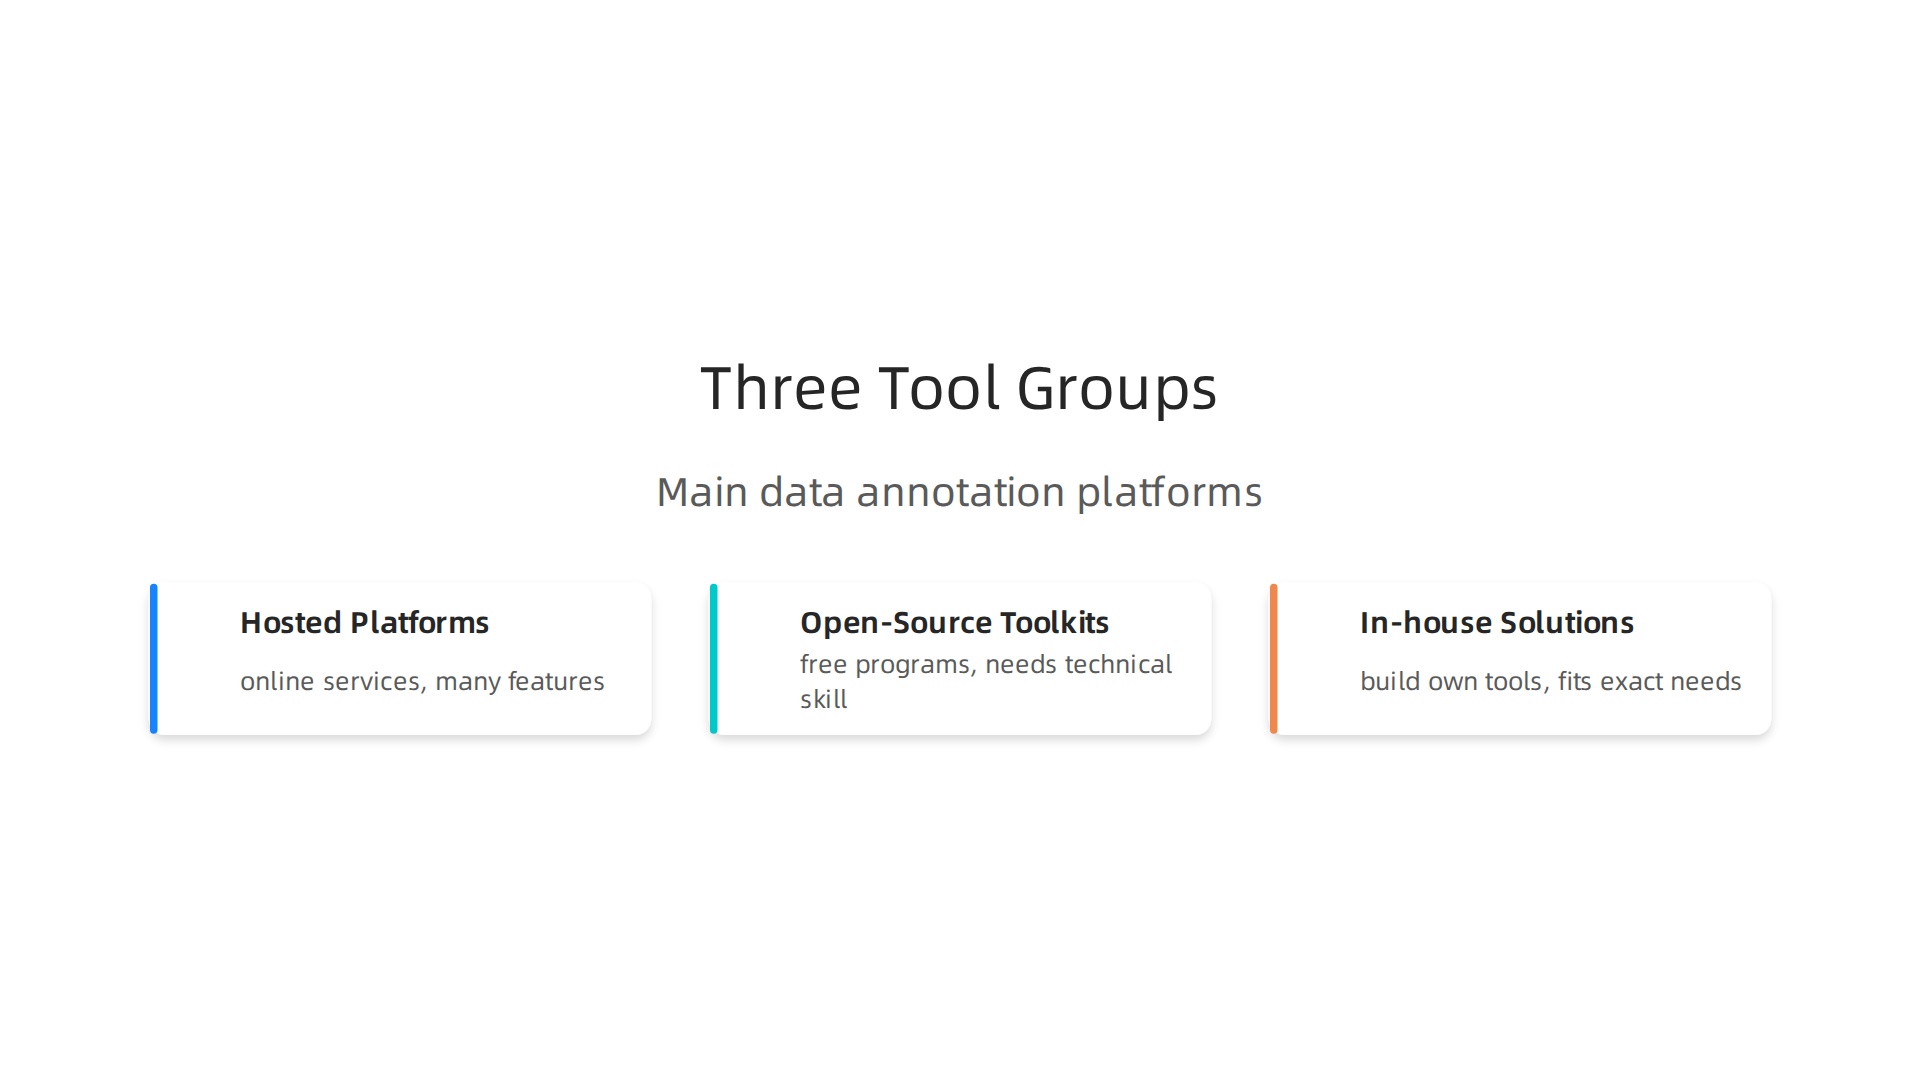
- Hosted Platforms: These are online services you pay for. They often come with many features built-in and handle all the technical stuff for you.
- Open-Source Toolkits: These are free programs that anyone can use and change. They need more technical skill to set up and run, but they offer a lot of control.
- In-house Solutions: Some larger companies build their own tools from scratch. This takes a lot of time and money but means the tool fits their exact needs perfectly.
When a data annotation specialist looks at these options, they think about different things. It’s like deciding if you should buy a ready-made car, build one yourself, or hire someone to build a special one.
What to Look for in Annotation Tools
A good tool helps the data annotation specialist do their job better. Here are some key things they check:
- What kind of data can it handle? Can it work with pictures, videos, sounds, or text? Many tools specialize, for example, some are best for PDF files, letting you add notes and highlights easily Best PDF Annotation Tools Compared (Free & Paid, 2026). Others are made for more complex AI needs like computer vision, handling images and video with advanced features 12 Best Data Annotation Tools for Computer Vision (Free & Paid).
- How easy is it to change how work flows? Can the tool be set up to match the team’s specific steps for labeling data? This is called workflow customization.
- Are there tools for checking quality? Features like Quality Assurance (QA) and ways to check if different labelers agree are very important. Some tools even keep track of every change and version of your data, like a history book for your labels Integrating Annotation Platforms Into MLOps.
- How much does it cost? This isn’t just about the price tag, but also how clear the pricing is. Are there hidden fees? This is called cost transparency.
- Can it work with other systems? Good tools should easily connect with other software used in the project. This is about integrations.
- How safe is the data? For important or private information, security is a must.
Choosing the right platform is critical. It impacts how quickly and well the data gets labeled, which then affects the AI’s learning. An associate data scientist, for instance, might rely heavily on these tools to prepare datasets for their models. This decision is a key part of understanding what is data science in a real-world setting, as it directly shapes the quality of the data that drives AI success. To deepen your understanding of how AI works and what roles contribute to its development, consider how different tools fit into the bigger picture of AI jobs 2026.
Staying informed about new AI models, tools, and research is vital for anyone in this field.
Get clear daily AI updates from The AI Newsletter Worth Reading.
After choosing the right tools, a data annotation specialist needs to make sure everyone understands how to use them. This means creating very clear rules for labeling data, called annotation guidelines. Good guidelines turn fuzzy ideas into exact steps, which is super important for making AI models learn correctly.
Making Annotation Rules Super Clear
Imagine you’re building a house and telling workers where to put the windows. If you just say "somewhere around the middle," you’ll get different results every time. It’s the same with data annotation. If the rules are not clear, different people will label the same data in different ways, which can mess up the AI’s learning.
Here’s how a data annotation specialist makes rules easy to follow:
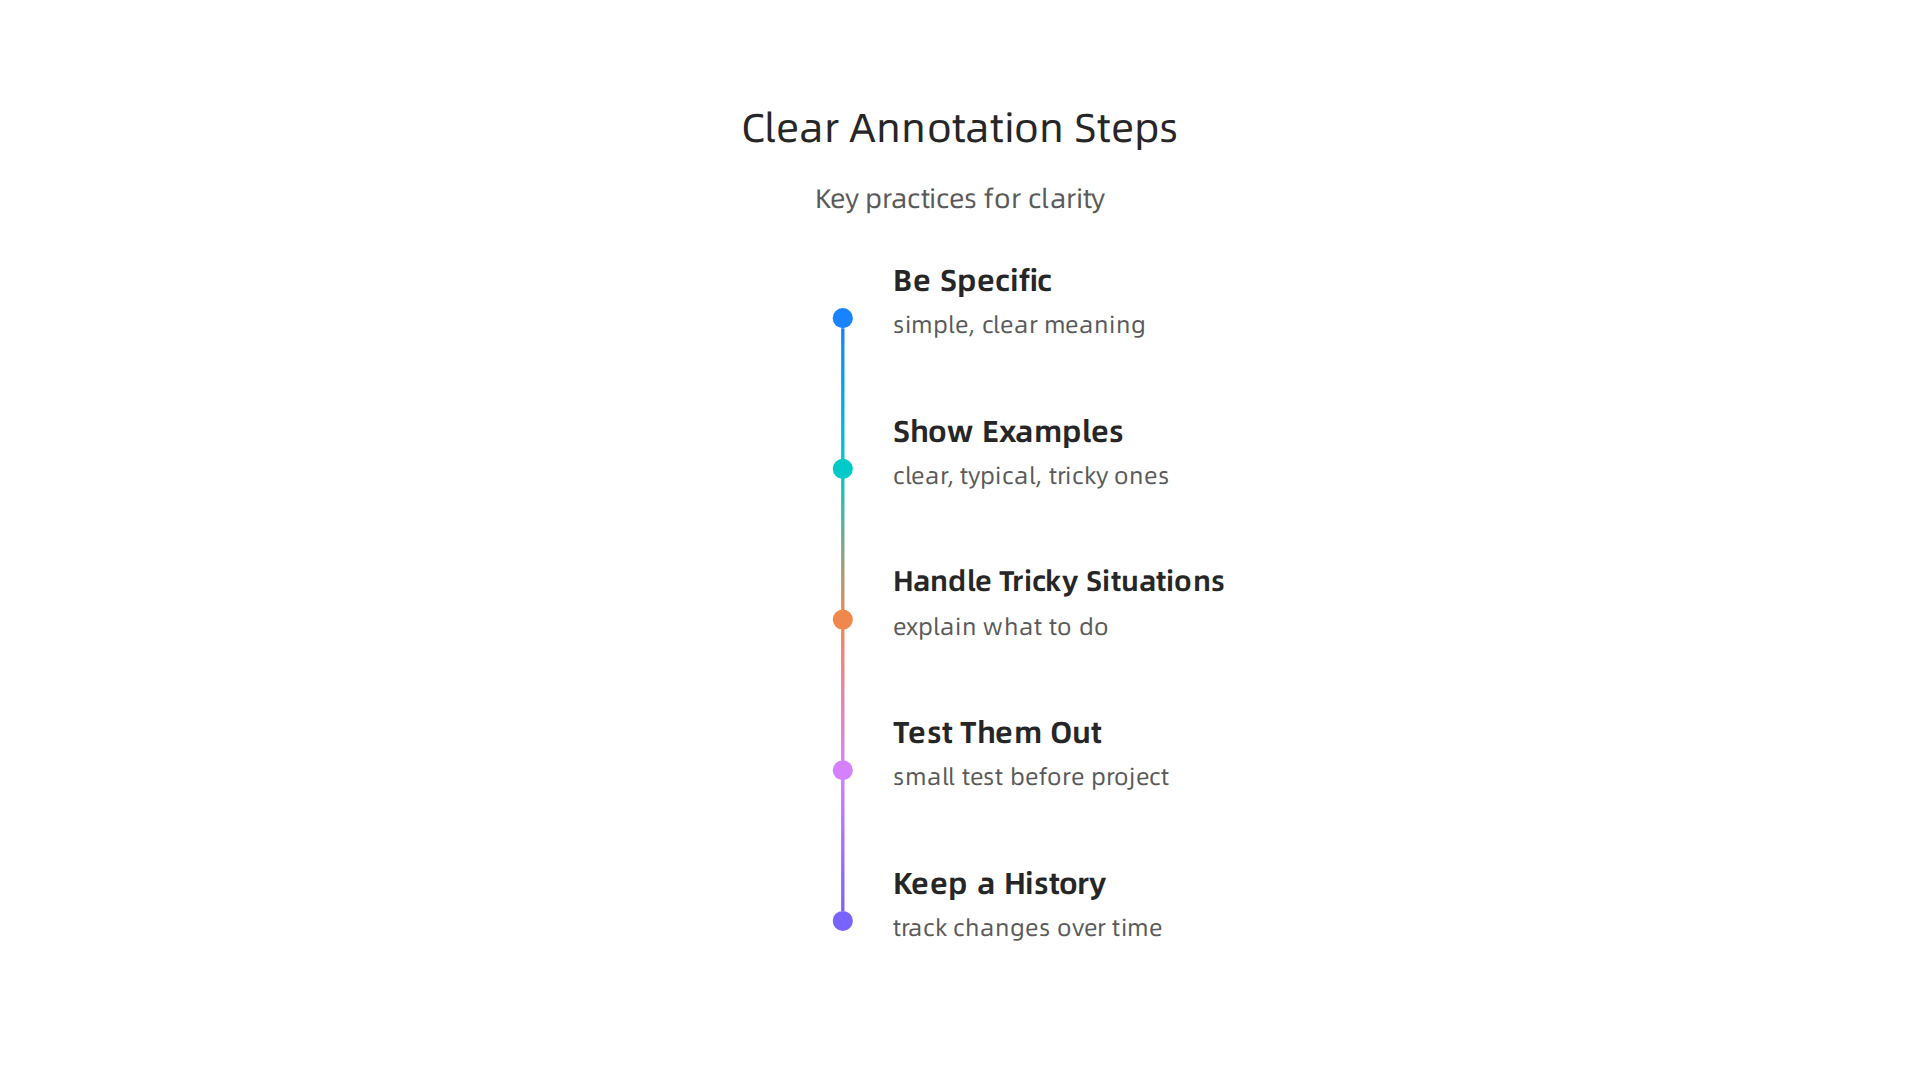
- Be Specific: Every type of label must have a simple, clear meaning. For example, if you’re labeling pictures of cars, define what makes something a "car" versus a "truck" AI Data Annotation Process: Step-by-Step Guide for 2026.
- Show Examples: It’s best to show many examples. Include clear examples, typical examples, and even tricky ones. It also helps to show bad examples and explain why they are wrong Data Annotation Guidelines: Ensuring Consistency with Clear ….
- Handle Tricky Situations: What if a picture shows only half a car? These are called "edge cases." The guidelines must explain exactly what to do in these unusual situations. Documenting these decisions helps everyone stay on the same page The Complete Guide to Data Annotation [2026 Review]. Sometimes, annotators can even mark when they are unsure, which helps later reviews A Human-in-the-Loop Audit of Annotation Errors in High-Stakes ….
- Test Them Out: Before a big project starts, a data annotation specialist will often do a small test. This helps find any confusing rules before too much work is done. This also involves creating standard templates for guidelines to keep things consistent across projects RE for AI in Practice: Managing Data Annotation ….
- Keep a History: Just like a good book has versions, guidelines might change over time. It’s important to track these changes so everyone uses the latest rules. This is like version control for your rules.
Building Quality Checks into the Work
Even with perfect guidelines, mistakes can happen. That’s why building Quality Assurance (QA) into the work is so important. QA makes sure the labeled data is correct and ready for the AI model. For an associate data scientist, using high-quality annotated data is key to building good models. This is part of what is data science in practice: ensuring data reliability.
Here’s how to build strong QA:
- Checking Samples: Not every piece of data can be checked, so a small, careful selection is reviewed regularly. This sample should be stable and include different types of data Annotation Quality Control: Practical 2026 Guide | LabelOp.
- When People Disagree (Adjudication): Sometimes, two different labelers might have different ideas about how to label the same data. An experienced data annotation specialist or senior reviewer will look at these cases and make a final decision. This process is called adjudication. It’s important to publish both the original labels and the final, agreed-upon labels for others to see Analyzing Dataset Annotation Quality Management in the ….
- Automated Checks: Some basic errors can be found by computers. For example, if a label is missing, or if a number is outside an expected range. These automated checks save time and catch simple mistakes fast Quality and SLAs – Avala Documentation – Avala AI.
- Fixing Mistakes: If many mistakes are found, there should be a plan to fix them. This might mean sending the data back to be re-labeled, giving more training to the annotators, or having a senior person step in to help Annotation Quality Assurance: 5 Ways to Measure ….
By having clear guidelines and strong QA, a data annotation specialist makes sure the data used for AI learning is as good as it can be. This directly impacts the success of AI projects and shows a deep understanding of the data science definition in real-world applications. To learn more about how specialists manage data for AI, read our article on Why Data Annotation Tech Is Critical For AI Accuracy.
After setting up clear rules and quality checks, the next big question for any data annotation specialist is: who will actually do all the labeling? For small projects, an in-house team might work. But often, projects are so big that they need many people, sometimes hundreds or even thousands. This is where scaling comes in. You have to decide if you want to hire your own team, use a special company, or get help from many people online.
Picking the Right Team: In-house, Vendors, or Crowdsourcing
There are three main ways to get data annotated when you have a lot of work:
- In-house team: This means you hire people directly to work for your company.
- Good for: When your data is very secret, or the work is super tricky and needs deep understanding of your business. It gives you the most control over quality and training.
- Things to think about: It can be expensive to hire and train many people. It also takes time.
- Managed vendors: These are companies that specialize in data annotation. They have their own teams, tools, and processes.
- Good for: Large projects that need a lot of work done fast, or tasks that require special skills. They often have quality checks built-in.
- Things to think about: You need to trust the vendor with your data and make sure their quality matches your needs.
- Crowdsourcing: This involves breaking down big tasks into many small ones and giving them to a large group of people online, often through platforms like Amazon Mechanical Turk.
- Good for: Simple, repetitive tasks that don’t need much training. It’s usually the fastest and cheapest option, with costs per label ranging from a few cents for basic bounding boxes to a bit more for image classification [Data Annotation Pricing 2026: Cost Per Label – SyncSoft.AI]. Some sources show basic bounding box tasks can cost as little as $0.02 to $0.10 per box in 2026 [Top 10 Data Labeling & Annotation Companies 2026 | Pricing].
- Things to think about: Quality can vary a lot, and data security might be a concern. It’s best used with good QA processes on your end to check the work.
Many companies, including those focused on AI, choose a mix of these options. An associate data scientist might start with smaller, easier tasks using crowdsourcing, while complex and sensitive data might stay with an in-house data annotation specialist. Understanding what is data science means knowing how to balance these different options for the best results.
Working with Outside Help: Important Rules to Set
When you decide to work with outside companies or crowdsourcing platforms, a data annotation specialist needs to set clear rules.
This helps make sure you get the quality you need without breaking the bank.
- Service Level Agreements (SLAs): These are like contracts that spell out how fast the work needs to be done and how good the quality must be. For example, it might say "95% accuracy within 3 days." This helps keep everyone on track.
- Sampling Plans: You can’t check every single piece of data if there are millions. So, you need a plan for checking a small, but fair, part of the data. This "sampling" helps you know if the overall quality is good [Data Annotation Outsourcing: How to Choose a Vendor (2026 Guide)]. Checking about 1% of your dataset can be a good start [15 Best Data Labeling and Data Annotation Companies – Voxel51].
- Data Security: Your data might be sensitive. Make sure any outside group you work with has strong rules to keep your data safe and private. This is a very important part of data science definition in the real world.
- Cost Versus Quality: Cheap isn’t always best. While costs for data labeling can vary greatly depending on the task and where the annotators are located [Data Labeling Pricing 2026: USA vs India], very low prices can mean lower quality. You need to find a balance where the cost is fair, but the quality is high enough for your AI models to learn correctly. For instance, per-label costs can vary widely, from $0.015 for simple keypoint annotations to much higher for more complex tasks [How data labeling pricing models compare].
By carefully choosing who labels your data and setting up clear rules for them, a data annotation specialist can make sure the AI project gets the best possible training data. This strategic approach helps manage costs and ensures high-quality results, which is crucial for building powerful AI. For professionals navigating the complexities of AI, staying updated on the latest developments is key.
Get clear daily AI updates from The AI Newsletter Worth Reading.
After setting up clear rules for how data should be labeled and who should do the work, a smart data annotation specialist also knows that different kinds of data need different ways of being handled. What works for pictures won’t always work for spoken words or 3D models. Understanding these special tasks is a big part of knowing what is data science in practice.
Here’s how different types of data annotation change the game:
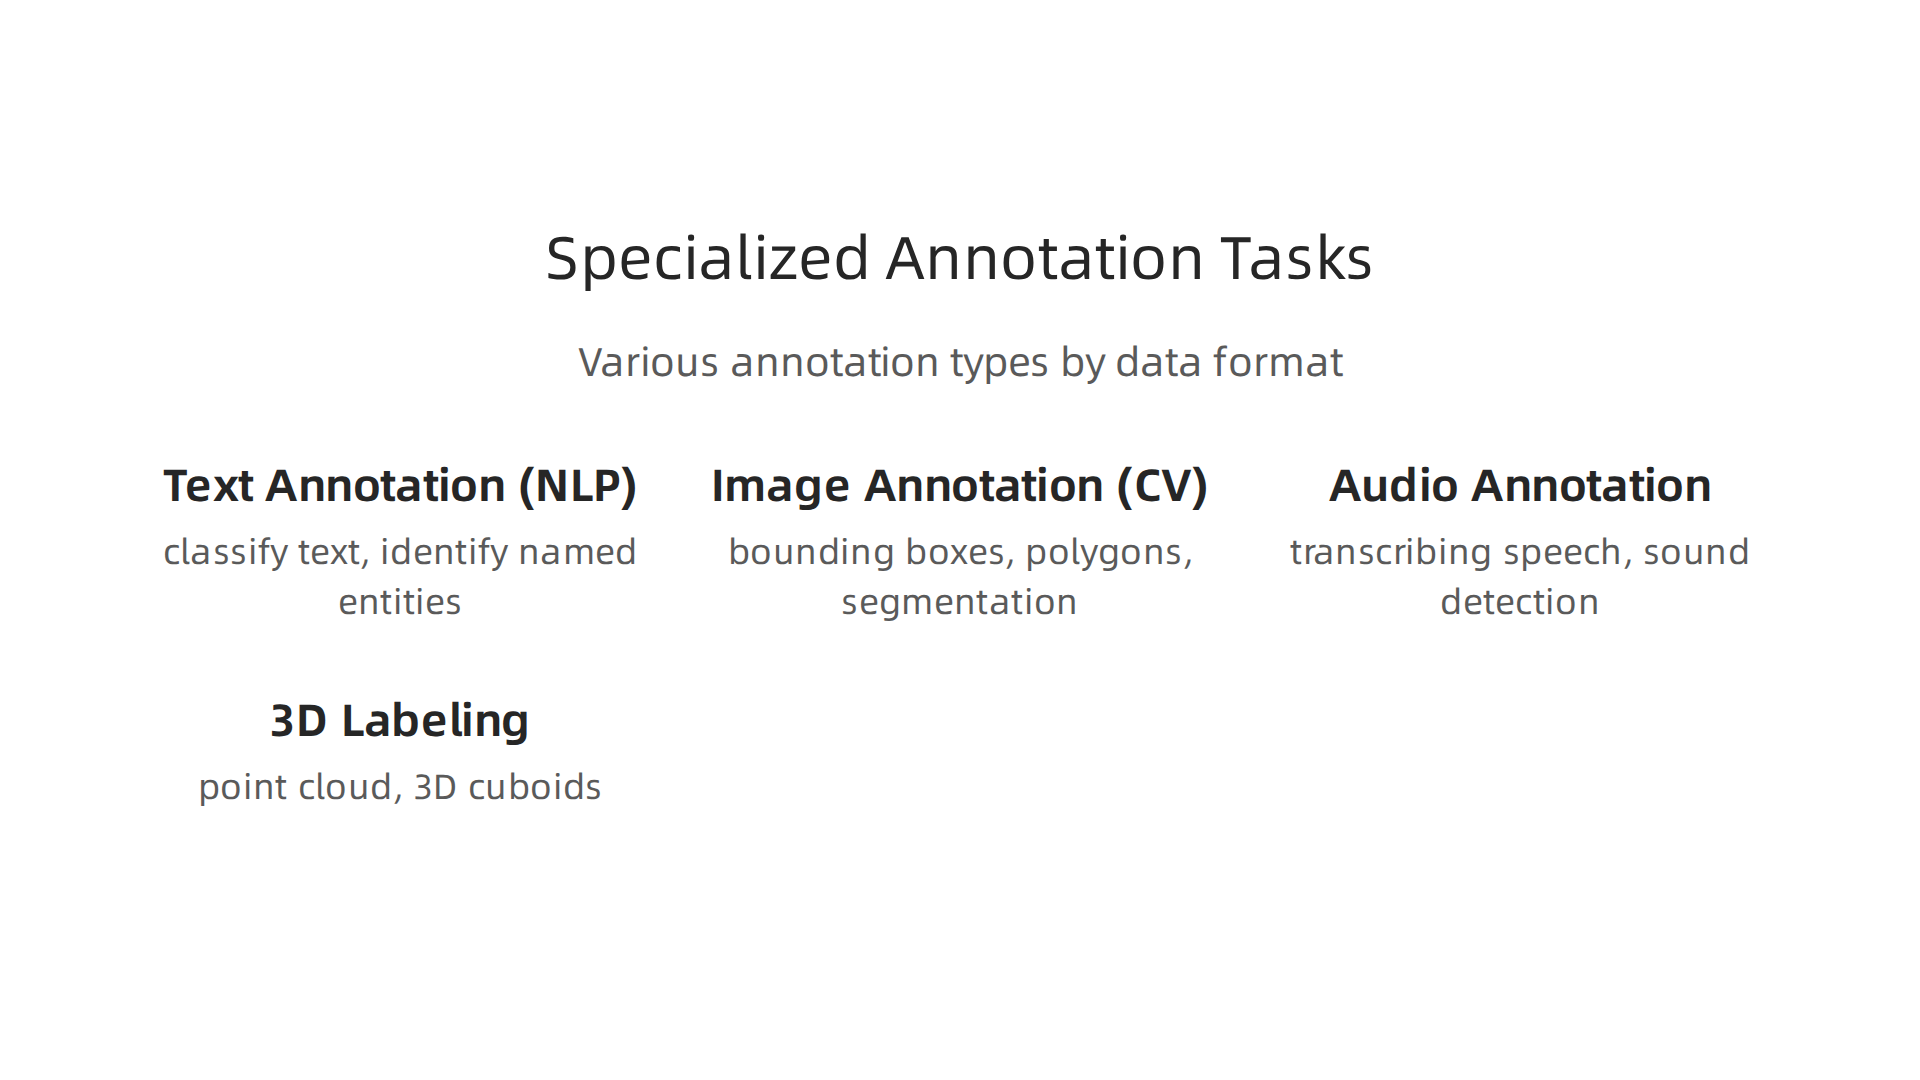
Text Annotation (Natural Language Processing or NLP)
When you’re working with text, like customer reviews or emails, you’re doing Natural Language Processing, or NLP. A data annotation specialist in this area might:
- Classify text: This means putting text into groups. For example, marking a review as "positive" or "negative."
- Identify named entities: This involves finding and labeling specific things in the text, like names of people, places, or companies. For example, marking "Apple Inc." as an organization.
The tricky part here is that words can be confusing. What one person thinks is a "negative" comment, another might see as just "neutral." This problem of label ambiguity means the rules must be super clear. It’s important to provide clear examples and guidelines for annotators to follow to ensure consistent labeling for machine learning models Natural Language Annotation for Machine Learning.
Image Annotation (Computer Vision)
For pictures and videos, you’re helping computers "see" things. This is called computer vision. An associate data scientist working with images might do:
- Bounding boxes: Drawing a box around objects, like a car in a photo.
- Polygons: Drawing more detailed shapes around objects that aren’t square, like a person.
- Semantic segmentation: Coloring in every pixel of an object to show its exact outline.
A common problem here is making sure everyone draws the boxes or shapes in the exact same way. Is the bounding box supposed to include the shadow? What if two objects are touching? Clear guidelines and examples are key to keeping labels uniform Annotation Quality Control: Practical 2026 Guide | LabelOp. Having a solid guide is like setting up an "ontology" which means defining all the classes and rules for how annotators should label things The Complete Guide to Data Annotation [2026 Review].
Audio Annotation
For sounds and speech, you’re teaching computers to "hear." This could involve:
- Transcribing speech: Turning spoken words into written text.
- Sound event detection: Marking when certain sounds happen, like a dog barking or a phone ringing.
The main challenge with audio is keeping everything in the right time order. Making sure the text matches up exactly with when the words were spoken in the audio can be hard. Different people might also hear or interpret sounds differently, which impacts quality.
3D Labeling (Spatial Data)
This is about helping AI understand the world in three dimensions, like for self-driving cars or robots. This often involves:
- Point cloud annotation: Labeling objects in a 3D space made of many tiny points.
- 3D cuboids: Drawing 3D boxes around objects in a point cloud or video to show their size and location in space.
This type of annotation is very complex and needs special tools and skills. It’s easy for small mistakes to throw off the whole 3D model, so precision is super important. The data science definition for these tasks often includes a deeper understanding of spatial awareness and technical tools.
No matter the data type, a skilled data annotation specialist knows that good planning and clear instructions are needed for high-quality data. This careful work is critical because it directly affects how well AI models learn and perform. For more details on why this work is so important, you can explore why data annotation tech is critical for AI accuracy.
After understanding the different ways to prepare data, it’s just as important to know how to check if that work is good. This means looking at quality, how much it costs, and what you get back from your investment. A good data annotation specialist always keeps an eye on these things. This is a core part of figuring out what is data science in a practical way.
Here are the important ways we measure how well data annotation programs are doing:
Key Measures for Annotation Quality
- Label Accuracy: This is simply how correct the labels are. For instance, if you’re marking cars in pictures, did the annotator correctly draw a box around every car? This is the most basic measure of quality.
- Inter-Annotator Agreement (IAA): Imagine two or more people label the same piece of data. IAA measures how much they agree. If they largely agree, it means your rules are clear and easy to follow. Low agreement can mean instructions aren’t clear or the task is too confusing, which hurts the quality of the data Data Labeling Quality Guide 2026: Metrics, Standards & Best Practices. High IAA helps make sure the results are steady and can be trusted.
- Error Type Distribution: It’s not just about if mistakes are made, but what kind of mistakes. Are people often missing small objects? Or are they labeling background noise as important sounds? Knowing the types of errors helps you improve your instructions and training for annotators.
- Throughput: This looks at how much work is being done in a certain amount of time. How many images are labeled per hour? How much text is processed each day? This helps understand the speed of the annotation team.
- Cost Per Useful Label: This metric combines cost and quality. It asks, "How much did it cost us to get one really good, correct label?" It helps you see if your money is being spent wisely to get high-quality data.
Linking Metrics to Model Impact
All these measurements are not just numbers for a data annotation specialist. They directly affect how well the AI models learn and perform. If the data used to train an AI model has many mistakes or is not consistent, the model will learn those mistakes. This means the AI might not work as well as expected, leading to poor decisions or unreliable results. Actually, poorly defined requirements for data annotation can truly hurt how well a model performs RE for AI in Practice: Managing Data Annotation ….
To make sure the data annotation is truly effective, it’s vital to link these metrics to the real-world performance of your AI models. This often means using a "model-in-the-loop" approach. Here, you use your AI model to help check and improve the labeling process. For example, if the model struggles with a certain type of data, you can send that data back to your human annotators for another look. This helps you get better data, which in turn makes your AI model smarter. This constant back-and-forth improvement is a key part of the data science definition in action. Learning about how to improve this process is part of your guide to mastering the data science process.
Keeping up with these insights and all the fast changes in AI is important for anyone working in this field.
Get clear daily AI updates from The AI Newsletter Worth Reading.
Summary
This article explains why practical data annotation is essential to build reliable AI and what a data annotation specialist actually does. It walks through the specialist’s core responsibilities — turning model needs into clear labeling tasks, writing and versioning annotation guidelines, selecting tools and platforms, and setting up QA processes like sampling and inter-annotator agreement. The guide covers how to scale annotation using in-house teams, vendors, or crowdsourcing, and it compares trade-offs around cost, security, and speed. You’ll also learn how different data types (text, images, audio, 3D) change annotation work and which metrics to track so your labeled data truly improves model performance.